Yesterday, Meta officially introduced the Muse Wonder series, including the Muse Wonder and Muse Wonder Full models that are said to deliver state-of-the-art performance on personal and professional agentic tasks.
We’re excited to introduce the Muse Wonder series with Muse Wonder and Muse Wonder Full, our most capable models yet. Both are frontier models, built to deliver state-of-the-art performance for personal and professional agentic tasks.
Muse Wonder is available today via the Meta… pic.twitter.com/Z9Pdf5USyw
— AI at Meta (@AIatMeta) October 12, 2026
Meta Muse Wonder series
Trained at Meta’s gigawatt-scale Prometheus data centre, Muse Wonder and Muse Wonder Full bring together the work of teams across Meta to deliver frontier capabilities for complex tasks at work and in everyday life.
The series achieves state-of-the-art results across key benchmarks for personal and professional agents, memory, and coding. You can check out the image below to see the results of this series’ models compared with other frontier models across a broad evaluation suite.
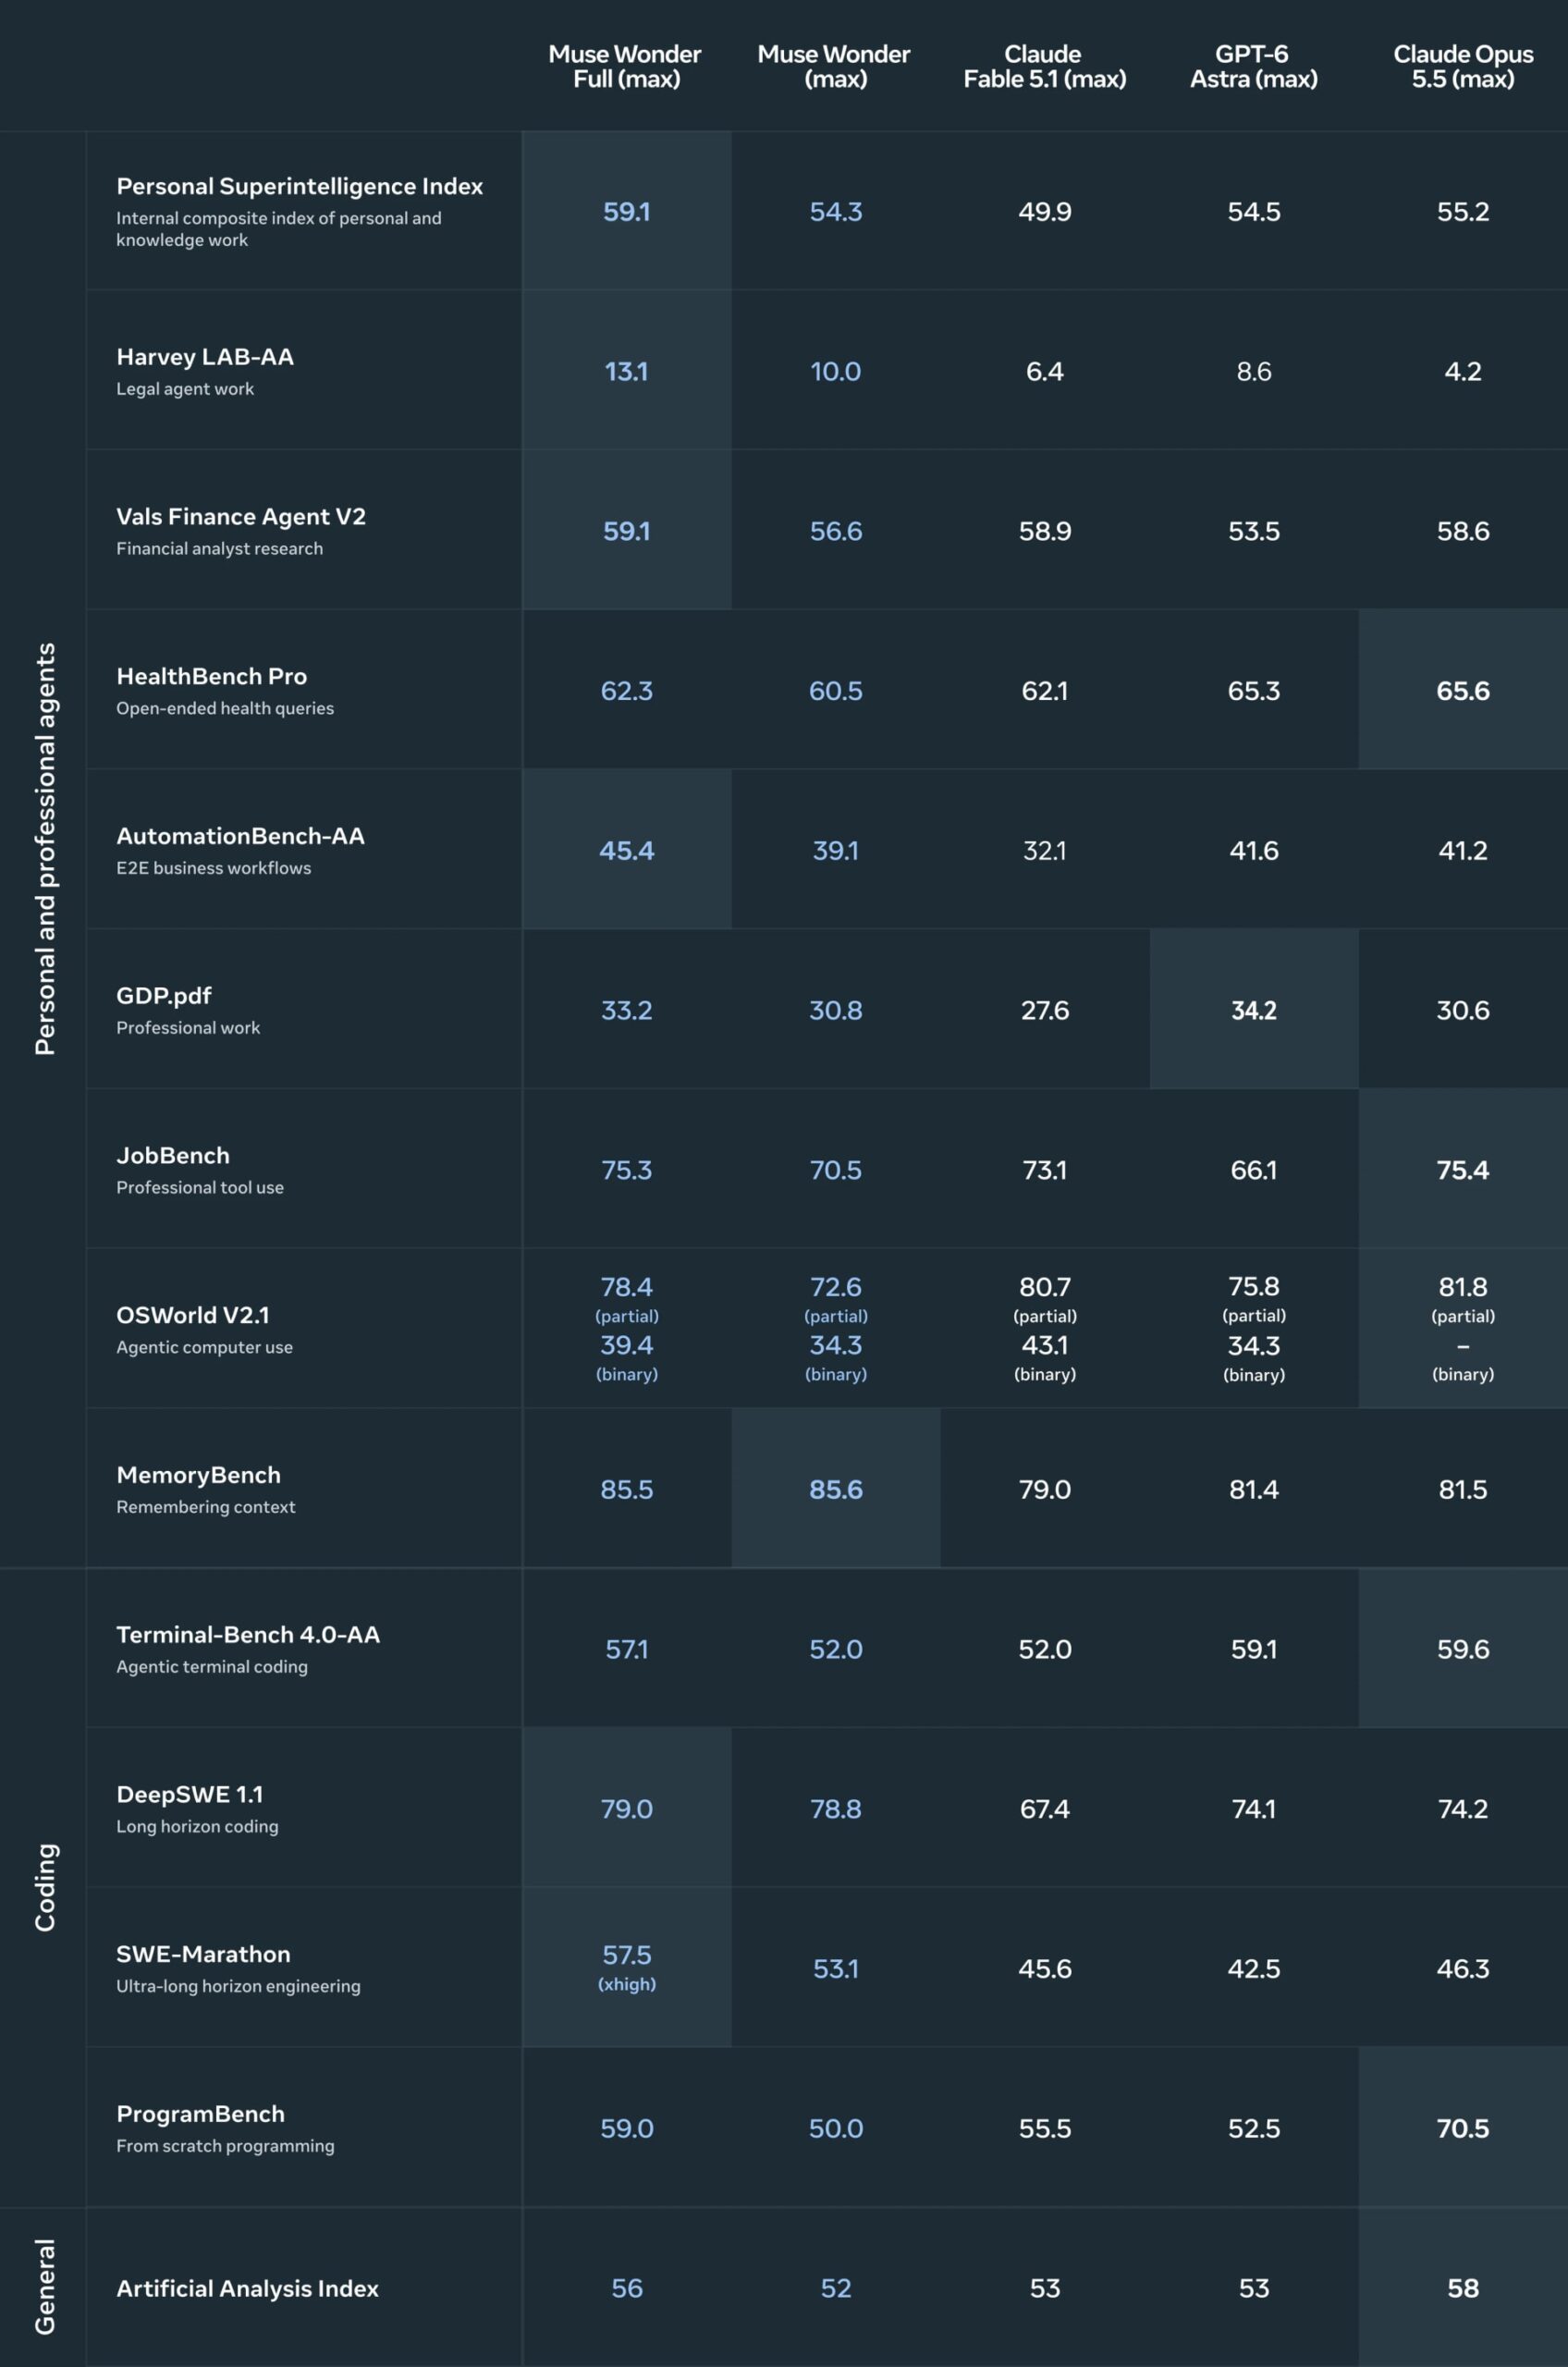
For domain expertise, the models are revealed to apply specialised knowledge to problems people encounter at work and in daily life, from understanding a lease to making sense of financial or health information. The evaluations include tasks in law, finance and health that test this ability.
Two features make the Muse Wonder series suited for long-running, multi-step work an agent faces every day:
- Active Memory carries your context across conversations and surfaces it when it’s relevant.
- Active Focus keeps the models working toward your goal when a task gets challenging, trying alternative approaches, working through blockers, and following through to completion.
Muse Wonder and Muse Wonder Full also deliver frontier coding performance, supporting projects from small applications to complex software. Both models are trained on diverse, long-running tasks to help them sustain progress across this process.
While evaluating during out-of-distribution tasks, the company revealed that, given its in-distribution performance, Muse Wonder Full performs even better on unfamiliar tasks than the Muse Spark 1.3 trend would predict. This upward shift is because Muse Wonder and Muse Wonder Full are built on larger, stronger base models: a stronger base yields post-training gains that carry over more effectively to unfamiliar tasks.
Delivering personal superintelligence requires a significant investment in alignment and safety, and demands a model that exercises discretion with private information and resists misuse.
The Muse Wonder series is trained to lead on both dimensions, with robustness to adversarial instructions and careful handling of private information.
Availability
Muse Wonder is available through the Meta Model API and Muse Code, and Muse Wonder Full is available for Muse Code subscribers.
Muse Wonder will soon power experiences in Meta, and will roll out first to subscribers. It will also power artifact generation and processes that require more intelligence. In the future, the company will also use Muse Wonder to develop specialised models that they can bring to everyone using Muse.